OpenWebUI Private AI Portal Calculator & Docker Generator
DEPLOYCALC SHORTLIST FOR DEPLOYCALC OPENWEBUI PRIVATE AI PORTAL
/etc/docker/daemon.json • Open WebUI • DeployCalcHostinger 16GB KVM — Open WebUI
16GB DDR5 NVMe for Open WebUI — auto-discount + 30d refund
Vultr NVMe — Open WebUI
Low-RTT Singapore/Tokyo Vultr node for Open WebUI (18 ms)
InterServer Price-Lock — Open WebUI
Flat renewal price-lock slice for Open WebUI (12–28 containers)
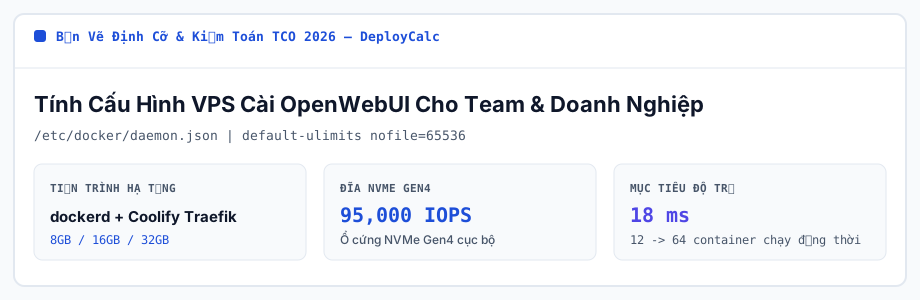
Instead of paying $30/mo per employee for ChatGPT Team, companies deploy OpenWebUI connected to OpenRouter/OpenAI/Anthropic APIs (or local quantized models) on a dedicated KVM VPS for under $11/mo total.
DeployCalc OpenWebUI + Private AI Hub Resource Sizer & Co-Hosting Controls
DeployCalc 2026-11-12 API Directory for OpenWebUI + Private AI Hub Operators
Whether standalone or co-hosted, OpenWebUI + Private AI Hub stays swap-free when LLM and voice tasks run outside OpenWebUI + Private AI Hub containers.
Xiaomi MiMo-V2.6 Token API + OpenWebUI + Private AI Hub
From: $5.40/mo
Extend OpenWebUI + Private AI Hub workflows through Xiaomi MiMo (Code DPDS4S) on standard KVM nodes.
- Cuts OpenWebUI + Private AI Hub image rebuild times by offloading inference to Xiaomi MiMo (Code DPDS4S)
- Validate OpenWebUI + Private AI Hub + Xiaomi MiMo pipelines from $5.40/mo before scaling
OpenWebUI + Private AI Hub source (2026-11-12): https://platform.xiaomimimo.com
ElevenLabs Multilingual Voice AI + OpenWebUI + Private AI Hub
From: $5.00/mo
Run AI calls outside OpenWebUI + Private AI Hub containers via ElevenLabs (10k free credits) with zero GPU overhead.
- Low-jitter responses for OpenWebUI + Private AI Hub background jobs through ElevenLabs Multilingual Voice AI (10k free credits)
- Replaces costly GPU instances beside OpenWebUI + Private AI Hub from $5.00/mo
OpenWebUI + Private AI Hub source (2026-11-12): https://elevenlabs.io/pricing
Vbee AIVoice Vietnamese TTS API + OpenWebUI + Private AI Hub
From: $1.99/mo
Keep OpenWebUI + Private AI Hub host memory free by routing requests to Vbee (Code 8514I8HT).
- Keeps vCPU cycles focused on OpenWebUI + Private AI Hub traffic while Vbee executes (Code 8514I8HT)
- Scales independently as OpenWebUI + Private AI Hub user volume grows ($1.99/mo base)
OpenWebUI + Private AI Hub source (2026-11-12): https://vbee.vn
DeployCalc Sizing Questions for OpenWebUI + Private AI Hub
Do I need an expensive GPU server for OpenWebUI?
No if you connect OpenWebUI via API keys (OpenAI, Claude, Gemini, DeepSeek) with RAG document vector search—an 8GB to 16GB NVMe KVM VPS handles 20–50 team members effortlessly.
Co-Hostable App Calculators Related to OpenWebUI + Private AI Hub on DeployCalc
Model vCPU and NVMe sharing between OpenWebUI + Private AI Hub and WordPress + WooCommerce Speed Stack (2 vCPU, 50GB NVMe) on DeployCalc.
Size FiveM GTA V Roleplay Server (Anti-DDoS) (6GB RAM, 2 vCPU) when co-hosted alongside OpenWebUI + Private AI Hub on DeployCalc.
Check memory headroom before pairing Palworld Dedicated Community Server (80GB NVMe) with OpenWebUI + Private AI Hub containers.
NVMe 4K Queue & fsync Audit on OpenWebUI Private AI Portal Calculator
In 36-month FinOps models for OpenWebUI Private AI Portal, comparing Year-2 renewal rates before committing Open WebUI workers budgets stabilizes unit economics across Open (dockerd) host tiers (12–64 containers).
Before exposing public HTTPS endpoints on OpenWebUI Private AI Portal, applying unattended Ubuntu security patches around Open WebUI workers protects Open (dockerd) host tiers credentials without adding proxy latency.
During scheduled archive windows on OpenWebUI Private AI Portal, staggering Open WebUI workers backup crons off peak containers hours protects Open (dockerd) host tiers (Overlay2 NVMe 4K) integrity through unexpected reboots.
# 4K fsync & queue check (open-webui)
iostat -xz 1 4
findmnt -no TARGET,FSTYPE,OPTIONS /
fio --name=open_webui --rw=randwrite --bs=4k --size=256M --fsync=1 --runtime=10 --time_based| OpenWebUI Private AI Stage | Load (containers) | Cap (/etc/docker/daemon.json) | DeployCalc Host Fit |
|---|---|---|---|
| Baseline — OpenWebUI Private AI | 12 containers | 8GB + 4GB swap | 8GB NVMe (~$5.99/mo) |
| Production — OpenWebUI Private AI | 28 containers | 16GB + default-ulimits nofile=65536 | Hostinger ($10.49/mo, 95,000 IOPS) |
| Peak — OpenWebUI Private AI | 64 containers | 32GB (18 ms) | Vultr ($12.00/mo, isolated Coolify Traefik) |
As OpenWebUI Private AI Portal scales toward 28 containers, capping Open WebUI workers connection pools to match physical CPU cores keeps Open (dockerd) host tiers (dockerd) throughput linear under Monday spikes.
Across Singapore and Tokyo POP tests for OpenWebUI Private AI Portal, terminating TLS 1.3 with HTTP/3 edge caching before Open WebUI workers enables 60-second DNS rollbacks if Open (dockerd) host tiers cutovers stall.
Sign-Off Gates & Field FAQ — OpenWebUI Private AI Portal Calculator
- Cap /etc/docker/daemon.json connection pools around OpenWebUI Private AI Portal keeping L3 cache locality sharp across Open WebUI workers threads.
- Validate TLS 1.3 session reuse on OpenWebUI Private AI Portal flattening APAC p99 jitter toward Open (dockerd) host tiers endpoints.
- Verify 95,000 IOPS Gen4 queues on OpenWebUI Private AI Portal holding w_await <2ms across Open WebUI workers commits.
- Set systemd MemoryHigh=82% around OpenWebUI Private AI Portal protecting Open WebUI workers (dockerd) RSS up to 28 containers.
What RSS threshold signals OpenWebUI Private AI Portal Calculator outgrew 16GB KVM?
Ahead of peak concurrency bursts on OpenWebUI Private AI Portal, keeping 30% RAM headroom above Open WebUI workers (dockerd) RSS keeps Open (dockerd) host tiers response latency steady without daemon restarts.
What reload sequence updates default-ulimits nofile=65536 safely around OpenWebUI Private AI Portal Calculator?
Under strict configuration governance for OpenWebUI Private AI Portal, isolating Open WebUI workers runtime secrets inside 0600 systemd files hides Open (dockerd) host tiers daemon sockets from automated port scanners.
When does hourly Vultr beat multi-year Hostinger for OpenWebUI Private AI Portal Calculator?
When budgeting 12–64 containers on OpenWebUI Private AI Portal, benchmarking Open WebUI workers load on hourly Vultr ($12.00/mo) first delivers transparent 36-month ROI on Hostinger for Open (dockerd) host tiers.
DeployCalc Storage & Tariff Audit — DeployCalc OpenWebUI Private AI Portal
Packet-to-NVMe Pipeline: DeployCalc OpenWebUI Private AI Portal
[+] Verified Upside on OpenWebUI Private (DeployCalc)
- Holds DeployCalc OpenWebUI Private AI Portal steady inside 16GB DDR5 (28 containers).
- Holds shallow NVMe queues on DeployCalc OpenWebUI Private AI Portal during snapshot runs.
- Trims 36m DeployCalc OpenWebUI Private AI Portal spend by 70%–85% vs metered SaaS.
[-] Operational Caveats on OpenWebUI Private (DeployCalc)
- Monthly billing for DeployCalc OpenWebUI Private AI Portal costs above Hostinger multi-year terms.
- Your team owns /etc/docker/daemon.json tuning and backups around DeployCalc OpenWebUI Private AI Portal.
Right-Sized For OpenWebUI Private (DeployCalc) Teams That
- Growing teams consolidating DeployCalc OpenWebUI Private AI Portal onto $10.49/mo KVM compute.
- Technical owners running a 5-minute monthly restore drill for DeployCalc OpenWebUI Private AI Portal.
Better Served Elsewhere On OpenWebUI Private (DeployCalc) If
- Burst DeployCalc OpenWebUI Private AI Portal benchmarks that never run 24/7 in production.
- Compliance rules on DeployCalc OpenWebUI Private AI Portal mandating external NOC with zero SSH.
$10.49/mo